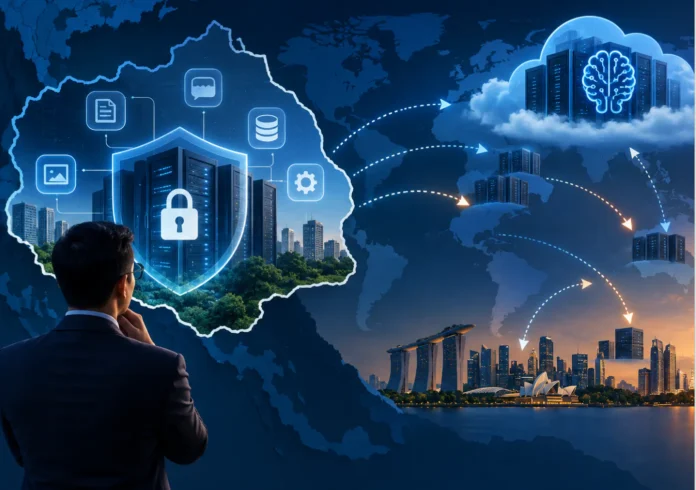
AI has complicated a question that once appeared relatively straightforward. Enterprise information can now move through prompts, embeddings, vector stores, model endpoints, monitoring systems and third-party services before an answer reaches a user. The primary database may remain firmly in-country while parts of the AI processing chain do not.
As generative AI moves deeper into regulated and business-critical operations, data sovereignty is becoming less about a location on a map and more about control: where information travels, which laws apply, who can access it and what evidence exists to prove those boundaries are being respected.
What residency, sovereignty and localisation actually mean
The terminology matters because residency, sovereignty and localisation describe different obligations.
Data residency refers to the geographic location where data is stored or processed. Organisations commonly select particular cloud regions to meet internal policy, customer or regulatory requirements.
Data sovereignty is broader. It concerns the legal and operational authority surrounding data, including the jurisdiction governing it, who may gain access and how much control an organisation retains over infrastructure, encryption and operations.
Data localisation usually involves a specific requirement for certain data to remain, and sometimes be processed, within a particular country or jurisdiction.
Cross-border transfer concerns data being transferred or disclosed to a recipient in another jurisdiction. Such transfers are not automatically prohibited. The EU, for example, provides mechanisms including adequacy decisions, Standard Contractual Clauses and Binding Corporate Rules. Singapore also sets requirements for transfers of personal data overseas.
Why AI creates more complicated data paths
Traditional residency reviews could concentrate heavily on databases, backups and disaster recovery. AI creates a much wider trail.
One enterprise AI request may travel through an application, retrieval system, vector database, model endpoint, safety layer and observability platform. A prompt could contain customer, employee or commercially sensitive information. The response may be logged. Embeddings and vector indexes can contain representations derived from source information, while telemetry can capture details about how the system is being used.
Training and fine-tuning widen the footprint further, adding datasets, checkpoints, evaluation environments and model artefacts. Microsoft’s sovereign AI guidance treats training data, embeddings, vector indexes, model weights and inference logs as assets that require deliberate residency and control decisions.
So the useful question is no longer simply, “Where is our data stored?” Enterprises need to know where each important AI data object can travel, where it is processed, how long it persists and who can reach it.
Architecture controls must follow the AI lifecycle
That changes the architecture conversation.
A strong sovereignty strategy must be backed by evidence. Organisations need clear records showing where data and AI assets are processed, who can access them, and how regional, encryption and retention controls are enforced. The same scrutiny should extend to third-party providers and subprocessors, creating a clear link between policy, contractual commitments and technical controls that can stand up to regulatory or audit review.
Audit evidence is as important as architecture
There is another test: can the organisation prove it?
A defensible sovereignty strategy needs evidence showing where datasets, model artefacts, backups, logs and derived information are stored and processed. Access records should reveal privileged activity. Configuration records should demonstrate regional restrictions, encryption settings, network controls and retention policies.
Third-party arrangements deserve equal attention. Organisations need visibility into subprocessors, support access, incident-response procedures and service features that might trigger processing outside an approved region.
The result should be a traceable line between policy, contractual commitments and technical configuration. Without that evidence, a well-designed sovereign architecture can become difficult to defend during an audit or regulatory review.
APAC requires a country-by-country view
Asia-Pacific adds another layer of complexity because there is no single regional rule governing data sovereignty.
Singapore’s PDPA places requirements on overseas transfers of personal data, while ASEAN has developed Model Contractual Clauses for cross-border data flows. In Australia, organisations covered by the Privacy Act generally have obligations when disclosing personal information to overseas recipients.
India’s Digital Personal Data Protection Rules, 2025 have added another important framework to the regional picture. APAC businesses handling data linked to European operations or individuals may also need to consider GDPR transfer requirements.
A blanket claim that an AI architecture is “APAC compliant” therefore says very little. The practical approach is a jurisdiction-by-jurisdiction view of data classes, transfer requirements, sector rules, approved locations and vendor dependencies.
Sovereignty is becoming an AI architecture question
Keeping data in-country still matters. It is simply no longer the whole answer.
The cloud region may still be printed on the map. The real measure of AI sovereignty is whether those boundaries can be demonstrated when it matters.
The new opening is deliberately more journalistic. It starts with a concrete cloud-region example rather than a generic “for enterprise technology leaders” introduction, then moves quickly into the problem the article is examining.