Google Cloud is betting on smarter data foundations and a truly open approach to AI-ready data.
In an interview with Andi Gutmans, the VP and GM for Data Cloud at Google Cloud laid out how Google is building a knowledge catalogue–centred architecture and a “borderless lakehouse” to tackle one of the hardest problems in enterprise AI – fragmented, expensive, and locked-in data estates.
“Every vendor says they’re open. We really are open,” Andi said “Customers want open ecosystems. They want open data platforms… they need the base platform to be open.”
From PHP to AI: Democratising the next generation of builders
EITN wanted to discover if there is a straight line from Andi’s early work co-founding PHP to what Google is trying to do with AI and data platforms today. We also recognised common themes around democratisation and the ‘vision’ to lower the barrier to entry.
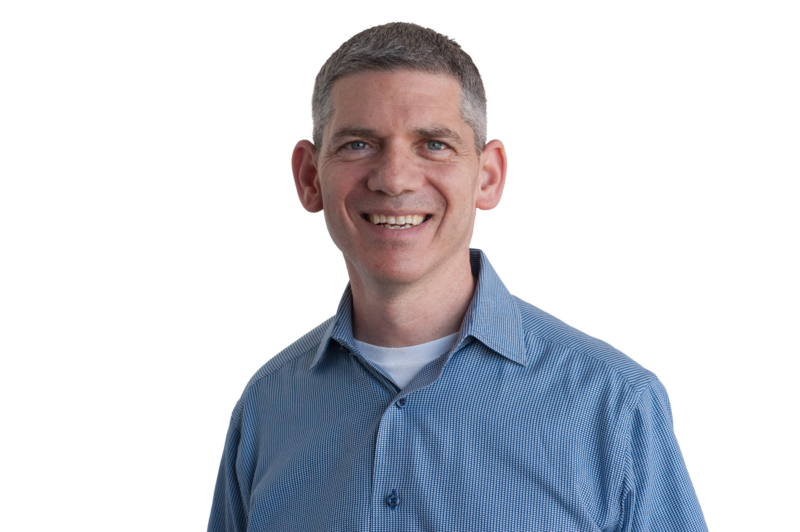
“One thing that was very exciting about the PHP journey was we really democratised web development,” Andi recalled “You don’t have to be a computer science graduate to go and build a web application with PHP.”
He sees generative AI as the next, even bigger, democratising wave.
“The same way PHP democratised web development… now we have the opportunity for AI to really democratise so many things that practitioners can do, without having to be the base expert,” he said.
Instead of developers or business users wrestling with infrastructure, tooling, and code, Andi described a shift from “AI as co-assistant” to “intent-driven outcomes”, where users specify what they want, and AI agents orchestrate the rest.
But there are caveats.
That orchestration only works if the underlying data and context are accessible, high quality, and affordable to use. That’s where Google’s knowledge catalogue and borderless lakehouse strategy comes in.
The problem: Messy, multi‑vendor, multi‑cloud data estates
Most large enterprises today have data sprawled across legacy systems and modern platforms – Oracle, SAP, SQL server, Snowflake, Databricks, multi-cloud object storage across AWS, Azure, Google Cloud, not to mention massive volumes of unstructured data.
“They each have a very messy estate,” Andi said. They’ve got data in Oracle, data in SAP, data in ServiceNow, probably data in Snowflake and Databricks, on other clouds, for example.”
Many vendors label themselves “open” simply because they support multi-cloud deployment. Andi rejects that definition as too narrow. He said, “You see all these vendors saying they’re open because they’re multi-cloud, but that doesn’t make them open. It just means they can run on multiple clouds.”
For enterprise AI, the real bottleneck is activating data where it already lives, without forcing wholesale migration, expensive egress, or tight lock-in to a single proprietary environment.
Borderless lakehouse – Breaking the “walled gardens”
Google’s answer is what Andi calls the “borderless lakehouse” – a rethinking of the traditional lakehouse model (data warehouse + data lake) to span vendors, formats, and locations.
“The reason why I call it a borderless lakehouse and not just a lakehouse is because it goes far beyond just the data warehouse–data lake piece,” he explained .
Key pillars of the borderless lakehouse include open table formats like Apache Iceberg to “…basically break down the walled gardens between Snowflake, Databricks, Amazon, Azure, for example,” Andi said. As long as data is in an open format, Google aims to offer a single entry point to it, regardless of which vendor’s engine is on top.
“We also use cross-cloud interconnects that are very cost-effective without egress costs to make sure you can do this in a cost-effective manner,” Andi said adding that they work closely with SaaS vendors like SAP, Workday and ServiceNow to bring their data into the borderless lakehouse with zero-copy integrations and without them having to pay high egress costs.
“We expand the notion of lakehouse to also include operational systems like Oracle systems, SQL server, Postgres… And then, lastly, we’re also bringing the on-premises environments into this environment.”
The term “borderless” serves as the defining element of this architecture – by dismantling the “walled gardens” that divide disparate systems, data can be unlocked and leveraged for AI regardless of where it resides.
This openness, removal of vendor lock-in, as well as potential cost savings is increasingly driving customer preference.
Knowledge catalogue: The “heart” of context for agentic AI
If the borderless lakehouse is how Google reaches data everywhere, the knowledge catalogue is how it turns that sprawl into usable context for AI agents.
Andi positioned the knowledge catalogue as central to context optimisation.
“We basically take a lot of the metadata about your data estate and your business, we use agents to enrich it, and it constantly learns with a feedback loop from the agents to understand how the context that we’re serving delivers both the quality outcomes and how much does it impact the reasoning.”
And this is where Google’s Search background comes in… to really make sure that we’re bringing the least amount of context that drives the highest amount of the best outcomes.
Andi Gutmans
Two areas of innovation stand out – agent-driven enrichment of enterprise knowledge and search-grade context retrieval. The first involves Google deploying agents to automatically enhance, classify, and relate metadata, so a dynamic knowledge layer is built over raw data which powers more precise, lower-cost reasoning.
“The second area of innovation, where I believe we’re most innovative in the market, is determining which context is retrieved for the agent. And this is where Google’s Search background comes in… to really make sure that we’re bringing the least amount of context that drives the highest amount of the best outcomes.”
Andi framed this as a “needle in the haystack” problem that Google is uniquely positioned to tackle, given its heritage in search.
The result? By surfacing only the most relevant context, Google aims to cut token consumption and minimise unnecessary MCP tool calls – helping address a significant and growing cost challenge for enterprise AI agents.
The context advantage
This year marks a meaningful shift in enterprise AI: vendors are increasingly promoting knowledge graphs, ontologies, semantic models and contextual layers as the foundations for more capable, reliable AI.
Against that backdrop, Andi positioned Google pragmatically as an open platform able to unify an organisation’s end-to-end data estate – rather than a point solution confined to its own proprietary engine and environment.
The company’s wider proposition is to become the context-rich foundation through which enterprises can orchestrate AI agents across fragmented data environments, wherever that data resides today.